- ホーム
- Microsoft
- DP-100J - Designing and Implementing a Data Science Solution on Azure (DP-100日本語版)
- Microsoft.DP-100J.v2025-06-23.q234
- 質問168
有効的なDP-100J問題集はJPNTest.com提供され、DP-100J試験に合格することに役に立ちます!JPNTest.comは今最新DP-100J試験問題集を提供します。JPNTest.com DP-100J試験問題集はもう更新されました。ここでDP-100J問題集のテストエンジンを手に入れます。
DP-100J問題集最新版のアクセス
「528問、30% ディスカウント、特別な割引コード:JPNshiken」
Azure ストレージ アカウント内の BLOB コンテナーを参照する training_data という名前のデータストアを作成します。BLOB コンテナーには、複数のコンマ区切り値 (CSV) ファイルが格納される csv_files という名前のフォルダーが含まれています。
./script というローカル フォルダーに train.py というスクリプトがあり、これを推定器を使用した実験として実行する予定です。スクリプトには、csv_files フォルダーからデータを読み取る次のコードが含まれています。
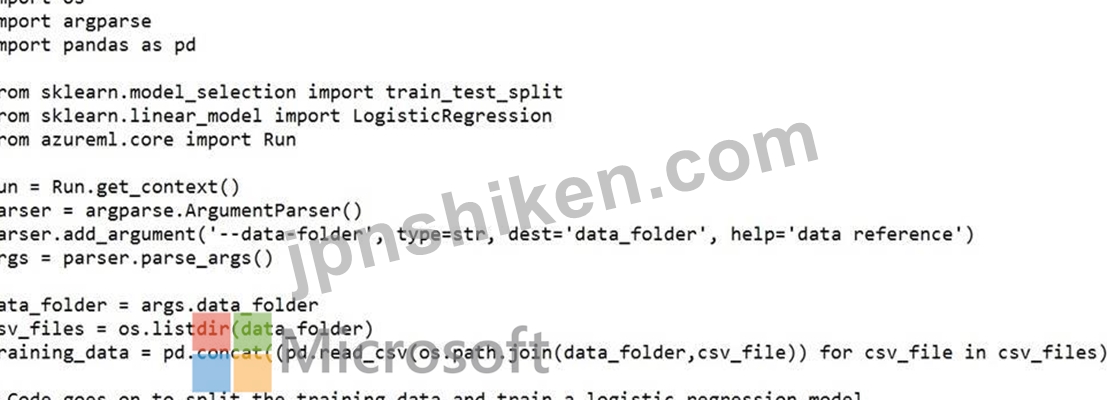
次のスクリプトがあります。
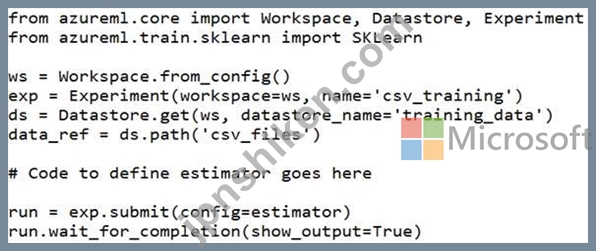
スクリプトが training_data データストアの csv_files フォルダーを参照する data_ref という名前のデータ参照からデータを読み取ることができるように、実験の推定値を構成する必要があります。推定値を
構成するにはどのコードを使用する必要がありますか?
./script というローカル フォルダーに train.py というスクリプトがあり、これを推定器を使用した実験として実行する予定です。スクリプトには、csv_files フォルダーからデータを読み取る次のコードが含まれています。
次のスクリプトがあります。
スクリプトが training_data データストアの csv_files フォルダーを参照する data_ref という名前のデータ参照からデータを読み取ることができるように、実験の推定値を構成する必要があります。推定値を
構成するにはどのコードを使用する必要がありますか?
正解:B
Besides passing the dataset through the inputs parameter in the estimator, you can also pass the dataset through script_params and get the data path (mounting point) in your training script via arguments. This way, you can keep your training script independent of azureml-sdk. In other words, you will be able use the same training script for local debugging and remote training on any cloud platform.
Example:
from azureml.train.sklearn import SKLearn
script_params = {
# mount the dataset on the remote compute and pass the mounted path as an argument to the training script
'--data-folder': mnist_ds.as_named_input('mnist').as_mount(), '--regularization': 0.5
}
est = SKLearn(source_directory=script_folder,
script_params=script_params,
compute_target=compute_target,
environment_definition=env,
entry_script='train_mnist.py')
# Run the experiment
run = experiment.submit(est)
run.wait_for_completion(show_output=True)
Incorrect Answers:
A: Pandas DataFrame not used.
Reference:
https://docs.microsoft.com/es-es/azure/machine-learning/how-to-train-with-datasets
Example:
from azureml.train.sklearn import SKLearn
script_params = {
# mount the dataset on the remote compute and pass the mounted path as an argument to the training script
'--data-folder': mnist_ds.as_named_input('mnist').as_mount(), '--regularization': 0.5
}
est = SKLearn(source_directory=script_folder,
script_params=script_params,
compute_target=compute_target,
environment_definition=env,
entry_script='train_mnist.py')
# Run the experiment
run = experiment.submit(est)
run.wait_for_completion(show_output=True)
Incorrect Answers:
A: Pandas DataFrame not used.
Reference:
https://docs.microsoft.com/es-es/azure/machine-learning/how-to-train-with-datasets

- 質問一覧「234問」
- 質問1 ホットスポットに関する質問 自動化された機械学習を使用して、
- 質問2 ドラッグアンドドロップの質問 ある組織は Azure Machine Learni...
- 質問3 ホットスポットに関する質問 アルゴリズムのハイパーパラメータ
- 質問4 パイプラインを実行する Python スクリプトがあります。スクリプ...
- 質問5 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問6 ディープラーニング仮想マシン (DLVM) を使用して、Compute Unif...
- 質問7 Azure Machine Learningのハイパードライブ機能を使用して、モデ...
- 質問8 ホットスポットに関する質問 ある都市の住宅販売データを含むデ
- 質問9 ホットスポットに関する質問 機械学習ソリューションを設計して
- 質問10 Azure Machine Learning Studio を使用して機械学習実験を構築し...
- 質問11 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問12 Azure Machine Learning ワークスペースを管理します。 MLflow ...
- 質問13 proj1 という名前の Azure Machine Learning ワークスペースを管...
- 質問14 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問15 Azure ML SDK を使用してバッチ推論パイプラインを作成します。 ...
- 質問16 Azure Machine Learning で自動化された機械学習を使用して、マ...
- 質問17 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問18 データセットに対して特徴エンジニアリングを実行しています。 C...
- 質問19 ホットスポットに関する質問 あなたはワイナリーにデータ サイエ...
- 質問20 ホットスポットに関する質問 自動車の価格データを含む Azure Ma...
- 質問21 ホットスポットに関する質問 Azure Machine Learning ソリューシ...
- 質問22 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問23 ホットスポットに関する質問 ローカル モデルの特徴抽出戦略を構...
- 質問24 ホットスポットに関する質問 大規模な糖尿病患者の年齢情報を含
- 質問25 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問26 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問27 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問28 ドラッグアンドドロップの質問 Azure Machine Learning デザイナ...
- 質問29 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問30 ある企業では、さまざまな種類のクラスターを使用してデータを処
- 質問31 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問32 ドラッグアンドドロップの質問 マルチクラス画像分類ディープラ
- 質問33 注: この質問は、同じシナリオを示す一連の質問の一部です。この...
- 質問34 GPUベースのトレーニングを使用して、Azure Machine Learningサ...
- 質問35 ホットスポットに関する質問 Azure Machine Learning Studio を...
- 質問36 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問37 AutoMLConfig クラスを使用して、最大 10 回のモデル トレーニン...
- 質問38 ドラッグアンドドロップの質問 Windows 用のディープラーニング...
- 質問39 ホットスポットに関する質問 x.1、x2、x3 機能に対して scikit-l...
- 質問40 トレーニング済みのモデルに対してリアルタイム推論サービスをデ
- 質問41 Azure Machine Learning ワークスペースを作成します。 ワークス...
- 質問42 ドラッグアンドドロップの質問 機械学習モデルを使用してインテ
- 質問43 デザイナーでパイプラインを作成し、自動車価格を予測するモデル
- 質問44 Azure Machine Learning ワークスペースを管理します。Responsib...
- 質問45 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問46 バッチ エンドポイントを含む Azure Machine Learning ワークス...
- 質問47 フィーチャエンジニアリングを行って、さらなる分析のためにデー
- 質問48 完成したバイナリ分類機械学習モデルを評価しています。 評価基
- 質問49 機械学習モデルをトレーニングして公開します。 外部システムか
- 質問50 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問51 Azure Machine Learning SDK for Python v1 とノートブックを使...
- 質問52 Azure Machine Learning 開発ワークスペースの一部としてコンピ...
- 質問53 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問54 ホットスポットに関する質問 CSV ファイルからのテキストを前処...
- 質問55 デザイナーを使用して新しい Azure Machine Learning パイプライ...
- 質問56 Azure Machine Learning ワークスペースを管理します。 Azure Da...
- 質問57 ホットスポットに関する質問 ノートブックからのモデル トレーニ...
- 質問58 あなたは、ホテル予約ウェブサイト会社で働くデータ サイエンテ
- 質問59 モデルのトレーニングに使用されるPythonコードを含むJupyterNot...
- 質問60 Azure Machine Learning Studio を使用してワークスペースを作成...
- 質問61 添付資料 A で指定された順序で処理する必要がある 5 つの Pytho...
- 質問62 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問63 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問64 ホットスポットに関する質問 データセットの構造が一致するよう
- 質問65 機械学習モデルをトレーニングして登録します。モデルを使用して
- 質問66 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問67 Azure Machine Learning ワークスペースを管理します。 MLflow ...
- 質問68 Azure Machine Learning ワークスペースを作成します。 離散ハイ...
- 質問69 ホットスポットに関する質問 Azure Machine Learning Python SDK...
- 質問70 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問71 複数のエポックにわたって畳み込みニューラル ネットワーク モデ...
- 質問72 Azure Machine Learning SDK を使用して、分類モデルをトレーニ...
- 質問73 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問74 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問75 CSV ファイルのセットには販売記録が含まれています。すべての C...
- 質問76 ホットスポットに関する質問 Azure Machine Learning を使用して...
- 質問77 Azure Machine Learning ワークスペースとサーバーレス Spark コ...
- 質問78 モデルをトレーニングするために、Azure Machine Learning コン...
- 質問79 注: この質問は、同じシナリオを示す一連の質問の一部です。この...
- 質問80 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問81 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問82 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問83 実験としてスクリプトを実行する予定です。スクリプトは、SciPy ...
- 質問84 ドラッグアンドドロップの質問 WS1 という名前の Azure Machine ...
- 質問85 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問86 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問87 ホットスポットに関する質問 Python で機械学習モデルを作成して...
- 質問88 ホットスポットに関する質問 Python SDK v2 を使用して、workspa...
- 質問89 ドラッグアンドドロップの質問 新しい Azure サブスクリプション...
- 質問90 分類モデルをトレーニングしたいデータを含むコンマ区切り値(CS...
- 質問91 Azure Machine Learning でトレーニング実験を実行する Python ...
- 質問92 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問93 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問94 英語のテキストコンテンツをフランス語のテキストコンテンツに翻
- 質問95 ノートブックからの Azure ML Python SDK v2 ベースのモデル ト...
- 質問96 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問97 Azure Machine Learning Studioの時系列データセットを使用して...
- 質問98 Azure Machine Learning ワークスペースを作成します。Azure Mac...
- 質問99 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問100 クラウド内の IoT データのリアルタイム分析を実行するソリュー...
- 質問101 Azure Machine Learning SDK for Python を使用して、2 段階の A...
- 質問102 ホットスポットに関する質問 Azure では、Windows および Linux ...
- 質問103 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問104 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問105 ホットスポットに関する質問 コンピューティング ターゲットとし...
- 質問106 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問107 ノートブックからのモデル トレーニングにベイジアン サンプリン...
- 質問108 Azure Machine Learning Studioを使用して、バイナリ分類モデル...
- 質問109 ホットスポットに関する質問 Azure Machine Learning Studio で...
- 質問110 あなたは線形回帰モデルを作成するデータ サイエンティストです
- 質問111 あなたは、鳥の健康と渡りを追跡するプロジェクトの主任データ
- 質問112 ローカルマシン上で機械学習プロジェクトを開発します。 このプ
- 質問113 Azure Machine Learning StudioからWeka環境に大きなデータセッ...
- 質問114 ドラッグアンドドロップの質問 CPU ベースのコンピューティング ...
- 質問115 ホットスポットに関する質問 Azure Machine Learning と SmartNo...
- 質問116 Azure ML SDK を使用してバッチ推論パイプラインを作成します。...
- 質問117 データセットに対してフィーチャエンジニアリングを実行していま
- 質問118 Azure Machine Learning ワークスペースを管理しています。サー...
- 質問119 Azure Machine Learning Studioを使用して機械学習実験を構築し...
- 質問120 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問121 Azure Machine Learning ワークスペースを作成します。表形式の...
- 質問122 ホットスポットに関する質問 モデル ファイルとスコアリング ス...
- 質問123 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問124 ホットスポットに関する質問 Azure Notebooks で train.classifi...
- 質問125 データ サイエンス プロジェクト用に Azure Machine Learning Ba...
- 質問126 モデル開発戦略を実装して、ユーザーが広告に反応する傾向を判断
- 質問127 Azure Machine Learningをサポートするには、Azure Blob Storage...
- 質問128 ScriptRunConfig オブジェクトを使用して、スクリプトを使用して...
- 質問129 ホットスポットに関する質問 Azure Machine Learning SDK for Py...
- 質問130 Azure Machine Learning ワークスペースを作成します。表形式の...
- 質問131 ホットスポットに関する質問 2,000 行を含むデータセットがあり...
- 質問132 音声認識の深層学習モデルを作成する予定です。 モデルはPython...
- 質問133 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問134 ホットスポットに関する質問 C-サポート ベクター分類を使用して...
- 質問135 イベント中の通話数を推定するための回帰モデルを構築しています
- 質問136 既存のモデルを再トレーニングします。 モデルの現在のバージョ
- 質問137 ホットスポットに関する質問 画像分類用のディープラーニング畳
- 質問138 ホットスポットに関する質問 分類タスクに取り組んでいます。生
- 質問139 ドラッグアンドドロップの質問 Azure Machine Learning デザイナ...
- 質問140 WS1 という名前の Azure Machine Learning ワークスペースがあり...
- 質問141 フォルダーを参照する csv_folder という名前のファイル データ...
- 質問142 Azure Machine Learning Designerを使用して、回帰モデルのトレ...
- 質問143 ドラッグアンドドロップの質問 WS1 という名前の Azure Machine ...
- 質問144 Azure Machine Learning スタジオでノートブックを作成していま...
- 質問145 あなたは、画像分類のための深い畳み込みニューラルネットワーク
- 質問146 ホットスポットに関する質問 Azure Machine Learning のリモート...
- 質問147 PyTorch 深層学習フレームワークを使用するマルチクラス画像分類...
- 質問148 チームデータサイエンス環境の構築を計画しています。機械学習パ
- 質問149 ドラッグアンドドロップの質問 Git リポジトリを使用して、Azure...
- 質問150 Workspace1 という名前の Azure Machine Learning ワークスペー...
- 質問151 ホットスポットに関する質問 Azure Machine Learning の Hyperdr...
- 質問152 ホテル予約ウェブサイトの不正取引を予測するための機械学習モデ
- 質問153 ホットスポットに関する質問 ビジネス アプリケーションで使用さ...
- 質問154 Azure Machine Learning を使用してモデルをトレーニングします...
- 質問155 ホットスポットに関する質問 パブリック エンドポイントからアク...
- 質問156 Azure Machine Learning ワークスペースを管理します。Azure Mac...
- 質問157 ドラッグアンドドロップの質問 機械学習ワークフローを自動化さ
- 質問158 Azure Machine Learning (ML) モデルがオンライン エンドポイン...
- 質問159 Azure Machine Learning ワークスペースを管理します。機械学習...
- 質問160 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問161 ホットスポットに関する質問 Azure Machine Learning を使用して...
- 質問162 ホットスポットに関する質問 回答エリアで正しいオプションを選
- 質問163 ドラッグアンドドロップの質問 Python SDK v2 を使用して、works...
- 質問164 株価を予測する機械学習モデルを実装しています。 このモデルは ...
- 質問165 ドラッグアンドドロップの質問 Azure Machine Learning Studio ...
- 質問166 ドラッグアンドドロップの質問 トレーニング エラー値と検証エラ...
- 質問167 Azure Machine Learning を使用してモデルをトレーニングします...
- 質問168 Azure ストレージ アカウント内の BLOB コンテナーを参照する tr...
- 質問169 Azure Machine Learning ワークスペースを管理しています。CSV ...
- 質問170 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問171 糖尿病の検査を受けた患者の記録を含むデータセットがあります。
- 質問172 ホットスポットに関する質問 Azure Machine Learning Studio で...
- 質問173 Azure Machine Learning ワークスペースを管理しています。既存...
- 質問174 機械学習モデルをトレーニングします。 テストのために、モデル
- 質問175 次のコードを実行して、Azure Machine Learning ワークスペース...
- 質問176 Azure Machine Learning SDK for Python を使用して、次の手順を...
- 質問177 自動機械学習を使用して回帰モデルをトレーニングする予定です。
- 質問178 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問179 ホットスポットに関する質問 次のリソースを含む Azure サブスク...
- 質問180 Azure Machine Learning ワークスペースに保存されているデータ...
- 質問181 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問182 ある企業が Azure Databricks を使用するソリューションを設計し...
- 質問183 ドラッグアンドドロップの質問 compute1 という名前のコンピュー...
- 質問184 ホットスポットに関する質問 Azure Machine Learning デザイナー...
- 質問185 ホットスポットに関する質問 Azure Machine Learning を使用して...
- 質問186 Azure Machine Learning Designerを使用して、トレーニングパイ...
- 質問187 MLflow モデルを作成します。 バッチ推論を行うには、モデルを A...
- 質問188 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問189 Azure Machine Learning で機械学習モデルをトレーニングしてい...
- 質問190 ドラッグアンドドロップの質問 Azure Machine Learning ワークス...
- 質問191 Azure Machine Learning Studioで新しい実験を作成しています。...
- 質問192 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問193 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問194 Azure Machine Learning ワークスペースを管理します。 ワークス...
- 質問195 ドラッグアンドドロップの質問 Azure Machine Learning プロジェ...
- 質問196 バイナリ分類モデルを作成します。 モデルの公平性を評価するに
- 質問197 ドラッグアンドドロップの質問 Azure Machine Learning Studio ...
- 質問198 ホットスポットに関する質問 近くの気象観測所からデータを収集
- 質問199 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問200 クラウドセンチメントローカルモデルの機能エンジニアリング戦略
- 質問201 ホットスポットに関する質問 ある人が病気にかかっているかどう
- 質問202 ドラッグアンドドロップの質問 150 を超える特徴を含むデータセ...
- 質問203 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問204 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問205 ドラッグアンドドロップの質問 群衆感情モデルの評価戦略を定義
- 質問206 ドラッグアンドドロップの質問 Workspace1 という名前の Azure M...
- 質問207 ドラッグアンドドロップの質問 Azure Machine Learning デザイナ...
- 質問208 ホットスポットに関する質問 同僚が次のコードを使用して、機械
- 質問209 Azure Machine Learning ワークスペースがあります。 MLflow モ...
- 質問210 Azure Machine Learning SDK v2 for Python とノートブックを使...
- 質問211 ホットスポットに関する質問 Azure Machine Learning Studio で...
- 質問212 ドラッグアンドドロップの質問 Azure Machine Learning ワークス...
- 質問213 Azure Machine Learning マネージド コンピューティング リソー...
- 質問214 銀行会社向けに、クレジットカード詐欺の可能性のある事例を識別
- 質問215 ホットスポットに関する質問 Azure Machine Learning を使用して...
- 質問216 クラスAの100個のサンプルとクラスBの10,000個のサンプルを含む...
- 質問217 注: この質問は、同じシナリオを提示する一連の質問の一部です。...
- 質問218 機械学習モデルを開発しています。 テストのために機械学習モデ
- 質問219 完成したバイナリ分類機械学習モデルを評価しています。 評価基
- 質問220 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問221 ホットスポットに関する質問 2 つの異なる年齢グループ内で糖尿...
- 質問222 バイナリ分類モデルを作成します。モデルは Azure Machine Learn...
- 質問223 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問224 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問225 ホットスポットに関する質問 Azure Machine Learning Service を...
- 質問226 分類タスクを解いています。 k分割交差検定を使用して、限られた...
- 質問227 ホットスポットに関する質問 Azure Machine Learning ワークスペ...
- 質問228 ホットスポットに関する質問 決定木アルゴリズムを使用していま
- 質問229 ホットスポットに関する質問 Azure Machine Learning を使用して...
- 質問230 Azure Machine Learning Studioを使用してデータセットを分析し...
- 質問231 企業向けのデータ エンジニアリング ソリューションを設計します...
- 質問232 スクリプト実行構成を使用して、実験としてスクリプトを実行する
- 質問233 ホットスポットに関する質問 コンピューティング クラスターを使...
- 質問234 K-meansアルゴリズムを使用してクラスタリングを実行しています...
