- ホーム
- Microsoft
- AI-102J - Designing and Implementing a Microsoft Azure AI Solution (AI-102日本語版)
- Microsoft.AI-102J.v2026-10-12.q183
- 質問156
有効的なAI-102J問題集はJPNTest.com提供され、AI-102J試験に合格することに役に立ちます!JPNTest.comは今最新AI-102J試験問題集を提供します。JPNTest.com AI-102J試験問題集はもう更新されました。ここでAI-102J問題集のテストエンジンを手に入れます。
AI-102J問題集最新版のアクセス
「425問、30% ディスカウント、特別な割引コード:JPNshiken」
Azure OpenA1 リソースを含む Azure サブスクリプションがあり、以下の設定を持つモデルを構成します。
* 温度: 1
* 最高確率: 0.5
* 最大レスポンストークン数: 100
モデルに質問すると、次の応答が返されます。

以下の各文について、正しい場合は「はい」を選択してください。そうでない場合は「いいえ」を選択してください。
注意: 正しい選択ごとにポイントが加算されます。
* 温度: 1
* 最高確率: 0.5
* 最大レスポンストークン数: 100
モデルに質問すると、次の応答が返されます。
以下の各文について、正しい場合は「はい」を選択してください。そうでない場合は「いいえ」を選択してください。
注意: 正しい選択ごとにポイントが加算されます。
正解:

Explanation:
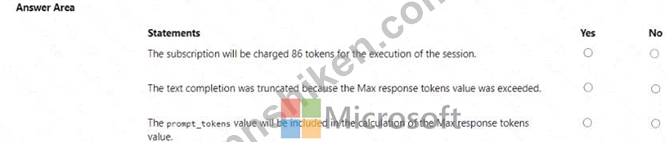
The subscription will be charged 86 tokens for the execution of the session. No The text completion was truncated because the Max response tokens value was exceeded. No The prompt_tokens value will be included in the calculation of the Max response tokens value. No From the response payload:
usage.prompt_tokens = 37
usage.completion_tokens = 86
usage.total_tokens = 123
finish_reason = " stop "
Billing is for total tokens (input + output), not just completion tokens.
Azure OpenAI bills on both prompt (input) and completion (output) tokens. Here, the total is 123 tokens, so it is not just 86. Hence No.
Not truncated by max response tokens.
If a response hits the maximum allowed output tokens, finish_reason would be " length " . Here it is " stop " and the model produced only 86 completion tokens while Max response tokens was set to 100, so the limit was not reached. Hence No.
max response tokens applies only to the generated output, not the prompt.
max_tokens (Max response tokens) limits the number of tokens the model may generate in the completion; it does not include prompt_tokens . Hence No.
Microsoft References
Azure OpenAI Service - Chat Completions API (parameters, max_tokens , response usage , finish_reason ).
https://learn.microsoft.com/azure/ai-services/openai/reference#chat-completions Azure OpenAI pricing and token usage model (charges for input and output tokens).
https://learn.microsoft.com/azure/ai-services/openai/overview#pricing
Token counting and limits (context vs. max output tokens).
https://learn.microsoft.com/azure/ai-services/openai/concepts/tokenizers#token-limits

- 質問一覧「183問」
- 質問1 Web ベースの顧客エージェントのユーザーからの自然言語入力を処...
- 質問2 テキストベースのチャットボットがあります。 Content Moderator...
- 質問3 Azure Al コンテンツ セーフティ リソースを含む Azure サブスク...
- 質問4 アプリのデプロイに使用する Pipeline1 という Azure DevOps パ...
- 質問5 Azure Stream Analyticsのストリーム処理ジョブでクエリを定義す...
- 質問6 Azure Al Languageでカスタム質問応答プロジェクトを開発します...
- 質問7 Resource1 という名前の Azure Al Language リソースを含む Azur...
- 質問8 あなたは、公開されているWebサイトからのビデオとテキストを処...
- 質問9 ローカル ドライブに保存されている File1.avi という名前の 20 ...
- 質問10 非リレーショナルデータベースの特徴は何ですか?
- 質問11 テキスト入力の意図を識別する Model という名前の Azure Cognit...
- 質問12 Azure Al Language を使用してテキスト メッセージから意味を抽...
- 質問13 Microsoft Bot Framework SDK を使用してボットを構築します。 ...
- 質問14 以下のデータソースがあります。 * 財務:オンプレミスのMicroso...
- 質問15 Azure Cognitive Service for Language に質問回答プロジェクト...
- 質問16 Azureサブスクリプションに、Azure AIコンテンツセーフティリソ...
- 質問17 Language Studio を使用して、要求の少ない会話型言語モデルを開...
- 質問18 感情分析と光学式文字認識(OCR)を実行するために使用する新し...
- 質問19 あなたは製品作成プロジェクトを計画しています。 ビデオを分析
- 質問20 bot1という名前の会話型ボットを作成します。 QnAMakerアプリケ...
- 質問21 Azure Al Language サービスを使用してドキュメントを分析するア...
- 質問22 DM という名前の Azure Al Document Intelligence リソースを含...
- 質問23 過去 24 時間のセンサー データの異常を検出するソリューション...
- 質問24 チャットボットがユーザー入力を適切なカテゴリに分類できること
- 質問25 ユーザーが画像をアップロードできるアプリを構築しています。ソ
- 質問26 ユーザー画像を共有するアプリを構築しています。 ユーザーが画
- 質問27 チャットボットを開発しています。 次のコンポーネントを作成し
- 質問28 Azureサブスクリプションをお持ちです。このサブスクリプション...
- 質問29 以下の方法を使用して、Azure AI Service リソースをプロビジョ...
- 質問30 カスタム ニューラル音声を使用する小売キオスク システムを構築...
- 質問31 次の JSON を使用して、Azure Cognitive Search のナレッジ スト...
- 質問32 あなたは旅行代理店用のチャットボットを構築しています。チャッ
- 質問33 CS1 という名前の Azure AI コンテンツ セーフティ リソースを含...
- 質問34 テキスト処理ソリューションを開発しています。 以下に示す関数
- 質問35 Azure Al Agent サービスを使用してエージェントを構築していま...
- 質問36 それぞれ独自の言語理解モデルを持つチャットボットが 100 個あ...
- 質問37 Azureサブスクリプションをお持ちの場合 ユーザーのプロンプトに...
- 質問38 Computer Vision API の呼び出しから取得した結果を検証するため...
- 質問39 Azure Cognitive Search を使用する Web アプリがあります。 ア...
- 質問40 技術的なポッドキャストの文字起こしサービスを構築しています。
- 質問41 テキストを含むスキャンされたドキュメント 50,000 件のコレクシ...
- 質問42 AS1 という名前の Azure Al Search リソースを含む Azure サブス...
- 質問43 AH という名前の Azure OpenAI リソースと CS1 という名前の Azu...
- 質問44 次の方法を使用して、Azure AI サービス リソースをプロビジョニ...
- 質問45 どのAzureストレージサービスがキー/値モデルを実装していますか...
- 質問46 Azure AIエージェントソリューションをお持ちです。 あなたは、...
- 質問47 次の要件を満たすチャットボットを構築する必要があります。 チ
- 質問48 食品を生産する工場を所有しています。 従業員の個人用保護具(P...
- 質問49 Azureサブスクリプションに、Resourcelという名前のAzure Al Lan...
- 質問50 文を正しく完成させる答えを選択してください。 (Exhibit)...
- 質問51 チケットを購入するための言語理解モデルを構築しています。 Pur...
- 質問52 アプリケーションの Text Analytics 出力を調べています。 分析...
- 質問53 Microsoft Bot Framework Composer を使用してチャットボットを...
- 質問54 スキャンした雑誌記事100万件を収録したアプリを開発しています...
- 質問55 Azure Cognitive Search インデックスの物理的な式を生成するに...
- 質問56 領収書画像を抽出するソリューションを開発する必要があります。
- 質問57 電子商取引チャットボット用の言語理解モデルを構築しています。
- 質問58 Face APIの呼び出しを開発しています。この呼び出しでは、既存の...
- 質問59 AH という名前の Azure OpenA1 リソースを含む Azure サブスクリ...
- 質問60 Azure AI 検索を使用する Web アプリがあります。 アクティビテ...
- 質問61 Azure AI Language サービスを使用してテキストを処理しています...
- 質問62 データ視覚化の2つの用途を食べたのは何ですか?それぞれの正解
- 質問63 ビデオ トレーニング ソリューションのコンテンツを作成していま...
- 質問64 Microsoft Bot Framework SDK と Azure Bot Service を使用して...
- 質問65 Windowsサーバー上の共有フォルダーにデータを保存するアプリケ...
- 質問66 ローカル ドライブに保存されている、file1、avi という名前の 2...
- 質問67 Azure Resource Manager (ARM) テンプレートを使用して Azure Op...
- 質問68 データストリームから温度データを監視するシステムを開発してい
- 質問69 注: この問題は、同じシナリオを提示する一連の問題の一部です。...
- 質問70 コンテナ ベース イメージを含む Host1 という名前の Docker ホ...
- 質問71 以下の各文について、正しい場合は「はい」を選択してください。
- 質問72 チャットボットの設計をレビューしています。チャットボットには
- 質問73 Resource1 という名前の Azure Al Speech サービス リソースがあ...
- 質問74 Azure サブスクリプションと 10,000 個の ASCII ファイルがあり...
- 質問75 RG1 という名前の新しいリソース グループに QnA Maker サービス...
- 質問76 Azure Cognitive Service for Language でカスタムの質問応答プ...
- 質問77 注: この問題は、同じシナリオを提示する一連の問題の一部です。...
- 質問78 顔認識APIを使用して従業員の顔を認識するアプリケーションを開...
- 質問79 スマート電子商取引プロジェクトを開発しています。 検索に PDF ...
- 質問80 Azure Al Vision クライアントライブラリを使用するアプリケーシ...
- 質問81 あなたの会社には、レポートをページングした植え替えソリューシ
- 質問82 Azure ai Language サービスを使用して音声翻訳を実行するアプリ...
- 質問83 Resource1 という名前の Azure Al コンテンツ セーフティ リソー...
- 質問84 テキスト分析に使用される Azure Cognitive Services サービスの...
- 質問85 受信メールを処理し、メール メッセージをフランス語または英語
- 質問86 画像が 100,000 枚あります。 次のアクションを実行するアプリを...
- 質問87 Microsoft Bot Frameworkを使用して、ローカルコンピューター上...
- 質問88 顧客データと注文データを組み合わせたSQLクエリがあります a。...
- 質問89 言語理解モデルを使用してテキスト ファイルを分析するアプリを
- 質問90 Foundry Tools サービスで Azure Translator を使用するメッセー...
- 質問91 文を正しく完成させる答えを選択してください。 (Exhibit)...
- 質問92 あなたはチャットボットを構築しています。 ボットが会社の製品
- 質問93 Azure AI を使用してワークスペースの安全規制コンプライアンス...
- 質問94 あなたは、Foundry Tools の Azure Document Intelligence を使...
- 質問95 注:この質問は、同じシナリオを提示する一連の質問の一部です。
- 質問96 以下の各記述について、正しい場合は「はい」を選択してください
- 質問97 外出先でのショッピング プロジェクトを開発しています。 QnA Ma...
- 質問98 A1 AH という Azure OpenA1 リソースがあり、GPT 3.5 モデルの 3...
- 質問99 コンテナにデプロイされた、app1 という名前の会話型言語理解ア...
- 質問100 AI1 という名前の Azure OpenAI リソースを含む Azure サブスク...
- 質問101 注: この問題は、同じシナリオを提示する一連の問題の一部です。...
- 質問102 Microsoft Bot Framework Composer を使用してチャットボットを...
- 質問103 どのデータベーストランザクションプロパティが、個々のトランザ
- 質問104 ソーシャル メディア メッセージング アプリを構築しています。 ...
- 質問105 Azure OpenAI リソースを含む Azure サブスクリプションがありま...
- 質問106 カスタム Azure OpenAI モデルがあります。 次の表に示すファイ...
- 質問107 Resource1 という名前の Azure AI コンテンツ セーフティ リソー...
- 質問108 言語理解ソリューションを構築しています。 多くのインテントに
- 質問109 チャットボットを開発しています。 次のコンポーネントを作成し
- 質問110 アンケートの感情分析結果を用いてカスタマーサービススタッフの
- 質問111 印刷されたフォームを管理するモバイル アプリがあります。 関連...
- 質問112 自然言語モデルを構築しています。 アクティブラーニングを有効
- 質問113 コンテナーにデプロイされた app1 という名前の Language Unders...
- 質問114 フィードバックを管理するアプリがあります。 Azure Cognitive S...
- 質問115 Face API を使用するアプリケーションを開発します。 人物グルー...
- 質問116 テキスト処理ソリューションを開発しています。 次の方法を開発
- 質問117 QnA Maker サービスを使用する小売チャットボットを構築していま...
- 質問118 英語からスペイン語にテキストを翻訳する、App1 という名前の Az...
- 質問119 発信者の母国語で応答できる自動通話処理システムを開発する必要
- 質問120 次のファイルがあります: * ファイル1.pdf * ファイル2.jpg * フ...
- 質問121 cu1 という名前の Azure AI コンテンツ理解リソースを含む Azure...
- 質問122 予期しないオペレーティングシステムの再起動時にデータベースへ
- 質問123 DM という名前の Azure Al Document Intelligence リソースを含...
- 質問124 次の形式でデータを保存しています。 (Exhibit) どのフォーマッ...
- 質問125 Search1 という名前の Azure Al Search リソースがあります。 Se...
- 質問126 Azure サブスクリプションをお持ちです。 ユーザーが画像を共有...
- 質問127 Azure Al Foundry エージェント サービスを使用してエージェント...
- 質問128 Microsoft Foundry リソースを含む Azure サブスクリプションが...
- 質問129 Computer Vision API を使用して画像を分析するアプリがあります...
- 質問130 リアルタイム推論のために、Azure Machine Learning のマネージ...
- 質問131 Microsoft OneDrive フォルダーに、FileVavi という 20 GB の動...
- 質問132 Azure Blob StorageからBLOBを自動的に削除するには、何を使用す...
- 質問133 次の構成の Azure サブスクリプションがあります。 * サブスクリ...
- 質問134 言語翻訳を含むアプリケーションを開発しています。 アプリケー
- 質問135 PDF ファイルとして保存されたプレス リリースのコレクションが...
- 質問136 Azure AI Foundryのコンテンツセーフティブロックリストを使用す...
- 質問137 次の C# 関数があります。 (Exhibit) 次のコードを使用して関数...
- 質問138 スマート電子商取引プロジェクトを開発しています。 Cognitive S...
- 質問139 テキストファイル、ビデオ、オーディオストリーム、および仮想デ
- 質問140 Appl という名前の Azure App Service アプリを含む Azure サブ...
- 質問141 URL からアクセスできる領収書があります。 Form RecognizerとSD...
- 質問142 App1 というアプリがあり、Azure Cognitive Services モデルを使...
- 質問143 あなたは、公開されているWebサイトからのビデオとテキストを処...
- 質問144 カスタム API を使用して、特定の場所の現在の時刻を取得するエ...
- 質問145 言語理解を使用するボットを構築しています。 次の内容を含む LU...
- 質問146 次の図に示すように、Microsoft Bot Framework Composer を使用...
- 質問147 AI1 という名前の Azure OpenAI リソースと User1 という名前の...
- 質問148 チャットボットを構築しています。 攻撃的または性的に露骨な言
- 質問149 ドキュメント処理ワークフローを開発しています。 財務文書から
- 質問150 文を正しく完成させる答えを選択してください。 (Exhibit)...
- 質問151 あなたの会社では、Azure Cognitive Services ソリューションを...
- 質問152 次の表に示すファイルを含むローカル フォルダーがあります。 (E...
- 質問153 QnA Maker アプリケーションを使用するチャットボットがあります...
- 質問154 Azure Al Translator サービスを使用して翻訳を実行するアプリを...
- 質問155 工場の生産ラインで製造された部品の欠陥を認識するアプリケーシ
- 質問156 Azure OpenA1 リソースを含む Azure サブスクリプションがあり、...
- 質問157 注: この問題は、同じシナリオを提示する一連の問題の一部です。...
- 質問158 英語(英国)で行われた講義を録画するサービスを開発しています
- 質問159 JavaScript でボットを構築します。 Azure コマンド ライン イン...
- 質問160 注文状況に関する顧客からの電話に応答するアプリを構築していま
- 質問161 resource1 という名前の Azure Al Foundry Content Safety リソ...
- 質問162 小売ドメインを使用して、会社の製品を識別するための Azure Cus...
- 質問163 注: この問題は、同じシナリオを提示する一連の問題の一部です。...
- 質問164 小売ドメインを使用して、会社の製品を識別する Custom Vision ...
- 質問165 Azure OpenAI GPT 3.5 モデルを使用するチャットボットを構築し...
- 質問166 アプリケーションの言語サービス出力を調べています。 分析され
- 質問167 休暇申請を行うためのアプリの会話型インターフェースを設計して
- 質問168 Microsoft Bot Framework を使用して構築され、Azure にデプロイ...
- 質問169 カスタム Form Recognizer モデルを構築します。 次の表に示すよ...
- 質問170 以下の各文について、正しい場合は「はい」を選択してください。
- 質問171 Azure Video Indexer サービスを使用するアプリを構築しています...
- 質問172 次のC#メソッドがあります。 (Exhibit) Azureリソースを米国東...
- 質問173 PDF 形式で保存されている人事 (HR) ポリシーに関する質問に答え...
- 質問174 resource1 という名前の Azure AI コンテンツ セーフティ リソー...
- 質問175 Azure SQL DatabaseなどのAzureで提供されるPaaS(Platform as a...
- 質問176 リレーショナルデータベースの主な特徴は何ですか?
- 質問177 製品作成プロジェクトのために画像をアップロードするためのコー
- 質問178 複数のアプリで使用される Search 1 という名前の Azure Cogniti...
- 質問179 Azure Al Anomaly Detector サービスを使用する監視ソリューショ...
- 質問180 データウェアハウスの主な目的は何ですか?
- 質問181 予測メンテナンスを実行する予定です。 100台の産業機械から1年...
- 質問182 セマンティックカーネルを使用してエージェントを構築します。エ
- 質問183 注: この問題は、同じシナリオを提示する一連の問題の一部です。...

