- ホーム
- Databricks
- Databricks-Certified-Data-Engineer-Professional-JP - Databricks Certified Data Engineer Professional Exam (Databricks-Certified-Data-Engineer-Professional日本語版)
- Databricks.Databricks-Certified-Data-Engineer-Professional-JP.v2025-11-25.q80
- 質問47
データ エンジニアリング チームは次のコードを管理しています。
Certified-Data-Engineer-Professional試験の最新かつ実際の質問と回答を入手する
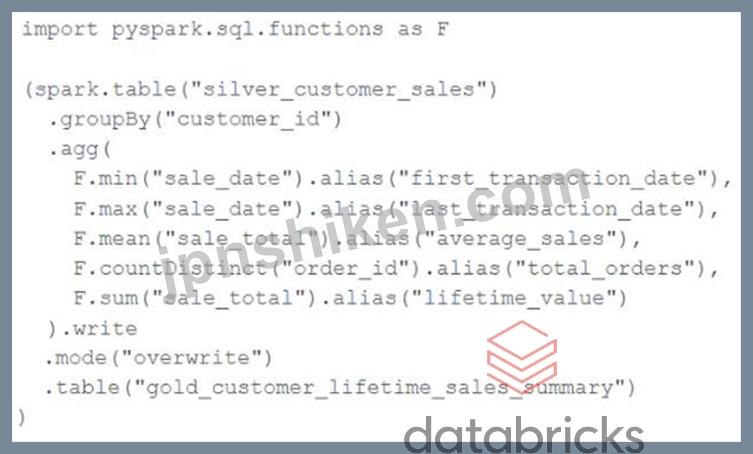
このコードが論理的に正しい結果を生成し、ソース テーブル内のデータが重複排除され検証されていると仮定すると、このコードを実行すると何が起こるかを説明するステートメントはどれですか。
Certified-Data-Engineer-Professional試験の最新かつ実際の質問と回答を入手する
このコードが論理的に正しい結果を生成し、ソース テーブル内のデータが重複排除され検証されていると仮定すると、このコードを実行すると何が起こるかを説明するステートメントはどれですか。
正解:C
This code is using the pyspark.sql.functions library to group the silver_customer_sales table by customer_id and then aggregate the data using the minimum sale date, maximum sale total, and sum of distinct order ids. The resulting aggregated data is then written to the gold_customer_lifetime_sales_summary table, overwriting any existing data in that table. This is a batch job that does not use any incremental or streaming logic, and does not perform any merge or update operations. Therefore, the code will overwrite the gold table with the aggregated values from the silver table every time it is executed.

- 質問一覧「80問」
- 質問1 運用ワークロードは、外部の変更データキャプチャフィードからの
- 質問2 データチームの構造化ストリーミングジョブは、下流のマーケティ
- 質問3 テーブルは次のコードで登録されます。 Certified-Data-Engineer...
- 質問4 ほぼリアルタイムのワークロードを容易にするために、データエン
- 質問5 ジュニアデータエンジニアが、Lakehouseのsilver_device_recordi...
- 質問6 ジュニアデータエンジニアの1人が、DataFrame dfを用いたグルー...
- 質問7 Databricksワークスペース管理者は、各データエンジニアリンググ...
- 質問8 データ エンジニアが数学関数のコレクションをテストしています
- 質問9 データガバナンスチームは、GDPR遵守のため、レコード削除に使用...
- 質問10 データエンジニアチームは、新しいデータパイプラインへの移行を
- 質問11 Spark へのデータの取り込み時に Spark パーティションのサイズ...
- 質問12 Databricks SQL ダッシュボードは、次のクエリ パターンを使用し...
- 質問13 上流システムは、特定のデータバッチの日付をパラメータとしてDa...
- 質問14 ジュニア データ エンジニアが、Databricks ジョブ UI を使用し...
- 質問15 データガバナンスチームは、個人識別情報(PH)を含むすべてのテ...
- 質問16 本番環境にデプロイされた構造化ストリーミングジョブにより、ク
- 質問17 必要なモジュールを見つけようとするときに検索するディレクトリ
- 質問18 Delta Lakeテーブルの下流のコンシューマーから、データ品質の問...
- 質問19 データエンジニアは、現在本番環境で使用されている複数のDatabr...
- 質問20 ユーザーからのコンテンツ投稿に関するメタデータを表す Delta L...
- 質問21 データエンジニアチームは、Databricksでサポートされているネイ...
- 質問22 データエンジニアリングチームのジュニアメンバーが、Databricks...
- 質問23 ジュニアデータエンジニアが、DataFrame dfを用いたグループ化さ...
- 質問24 ジュニア データ エンジニアが、次の JSON を Databricks REST A...
- 質問25 1時間ごとのバッチジョブは、クラウドオブジェクトストレージコ
- 質問26 データエンジニアリングチームのメンバーが、より大規模なデータ
- 質問27 Sparkジョブの実行時間が予想よりも長くなっています。データエ...
- 質問28 本番環境データへの偶発的なコミットを防ぐため、シニアデータエ
- 質問29 述語プッシュダウンを活用しないことによって発生するパフォーマ
- 質問30 Lakehouse内のcustomer_churn_paramsというテーブルは、機械学習...
- 質問31 ビジネスレポート作成チームでは、ダッシュボードのデータを1時
- 質問32 データガバナンスチームは、GDPR遵守のため、ユーザーのレコード...
- 質問33 次のエラー トレースバックを確認します。 Certified-Data-Engin...
- 質問34 Databricks プラットフォーム上の Spark 構成に関して正しい記述...
- 質問35 統合テストについて説明している記述はどれですか?
- 質問36 データサイエンスチームから、ユーザーレビューの自由形式テキス
- 質問37 ビューの更新は、顧客テーブルに挿入または更新される新しく取り
- 質問38 Databricksジョブは3つのタスクで構成されており、それぞれがDat...
- 質問39 Spark Structured Streaming で使用される一般的なプログラミン...
- 質問40 ある大企業は、膨大な量と高速のデータを持つ多数のテーブルを並
- 質問41 マルチタスク ジョブでタスクとして実行するように構成されたノ
- 質問42 データサイエンスチームはMLflowを使用して本番環境モデルを作成...
- 質問43 テキスト エディターで表示した場合、Databricks Python ノート...
- 質問44 データエンジニアのユーザーAは、REST APIを使用してプログラム...
- 質問45 Databricksジョブは3つのタスクで構成されており、それぞれがDat...
- 質問46 エンドツーエンド テストの主な利点を説明している記述はどれで
- 質問47 データ エンジニアリング チームは次のコードを管理しています。...
- 質問48 データエンジニアリングチームは、顧客からの忘れ去られる(デー
- 質問49 Databricks CLI が正しくインストールされ、構成されていると仮...
- 質問50 ビューの更新は、顧客テーブルに挿入または更新される、新しく取
- 質問51 夜間ジョブは、次のコードを使用して Delta Lake テーブルにデー...
- 質問52 データエンジニアリングチームは、数千のテーブルとビューを含む
- 質問53 ストリーム静的結合と静的デルタ テーブルに関する正しい記述は
- 質問54 データ エンジニアリング チームは次のコードを管理しています。...
- 質問55 次の表は、電子商取引 Web サイト内のユーザー カートにあるアイ...
- 質問56 現在アクティブなクラスター内のすべてのノードに、ノートブック
- 質問57 アップストリームソースは、Parquetデータを1時間ごとのバッチと...
- 質問58 Databricks はカスタム Python コード パッケージのインストール...
- 質問59 Spark ドライバーの log4j 出力を解析するときに、テキストの重...
- 質問60 データ エンジニアは、非常に類似したコードによる複数の定義が
- 質問61 次のロジックを使用して、activity_details という名前の Delta ...
- 質問62 Lakehouse内のDelta Lakeテーブル「customer_parsams」は、機械...
- 質問63 タスクオーケストレーターは、2つの1時間ごとのタスクを実行する...
- 質問64 データアーキテクトは、2つの構造化ストリーミングジョブが単一
- 質問65 データ アーキテクトは、Lakehouse 内のすべてのテーブルを外部 ...
- 質問66 pyspark.sql.functions.broadcast の正しい使用方法を説明してい...
- 質問67 データエンジニアは、ワークスペース内の既存のパイプライン設定
- 質問68 新人データエンジニアが、KafkaソースをDelta Lakeに書き込むア...
- 質問69 Apache Kafka プロデューサーからのすべてのレコードは、次のス...
- 質問70 データ アーキテクトは、Lakehouse 内のすべてのテーブルを外部 ...
- 質問71 ストレージとコンピューティングのコストを削減するために、デー
- 質問72 データ エンジニアは、遅れて到着する重複レコードが表示される
- 質問73 データ エンジニアのチームは、多くの同じデータ品質チェックに
- 質問74 ジョブ実行履歴の保持に関して正しい記述はどれですか?
- 質問75 Databricks で最も一般的なデータの場所の 2 つは、DBFS ルート ...
- 質問76 ジュニア開発者が、ノートブック内のコードが開発環境で正しい結
- 質問77 本番環境にデプロイされた構造化ストリーミングジョブで、ピーク
- 質問78 データ エンジニアは、静的な userlookup テーブルの値をストリ...
- 質問79 本番環境で構造化ストリーミング ジョブをスケジュールする場合
- 質問80 データ取り込みタスクでは、1TBのJSONデータセットをParquetに書...

[×]
Download PDF File
Enter your email address to download Databricks.Databricks-Certified-Data-Engineer-Professional-JP.v2025-11-25.q80.pdf